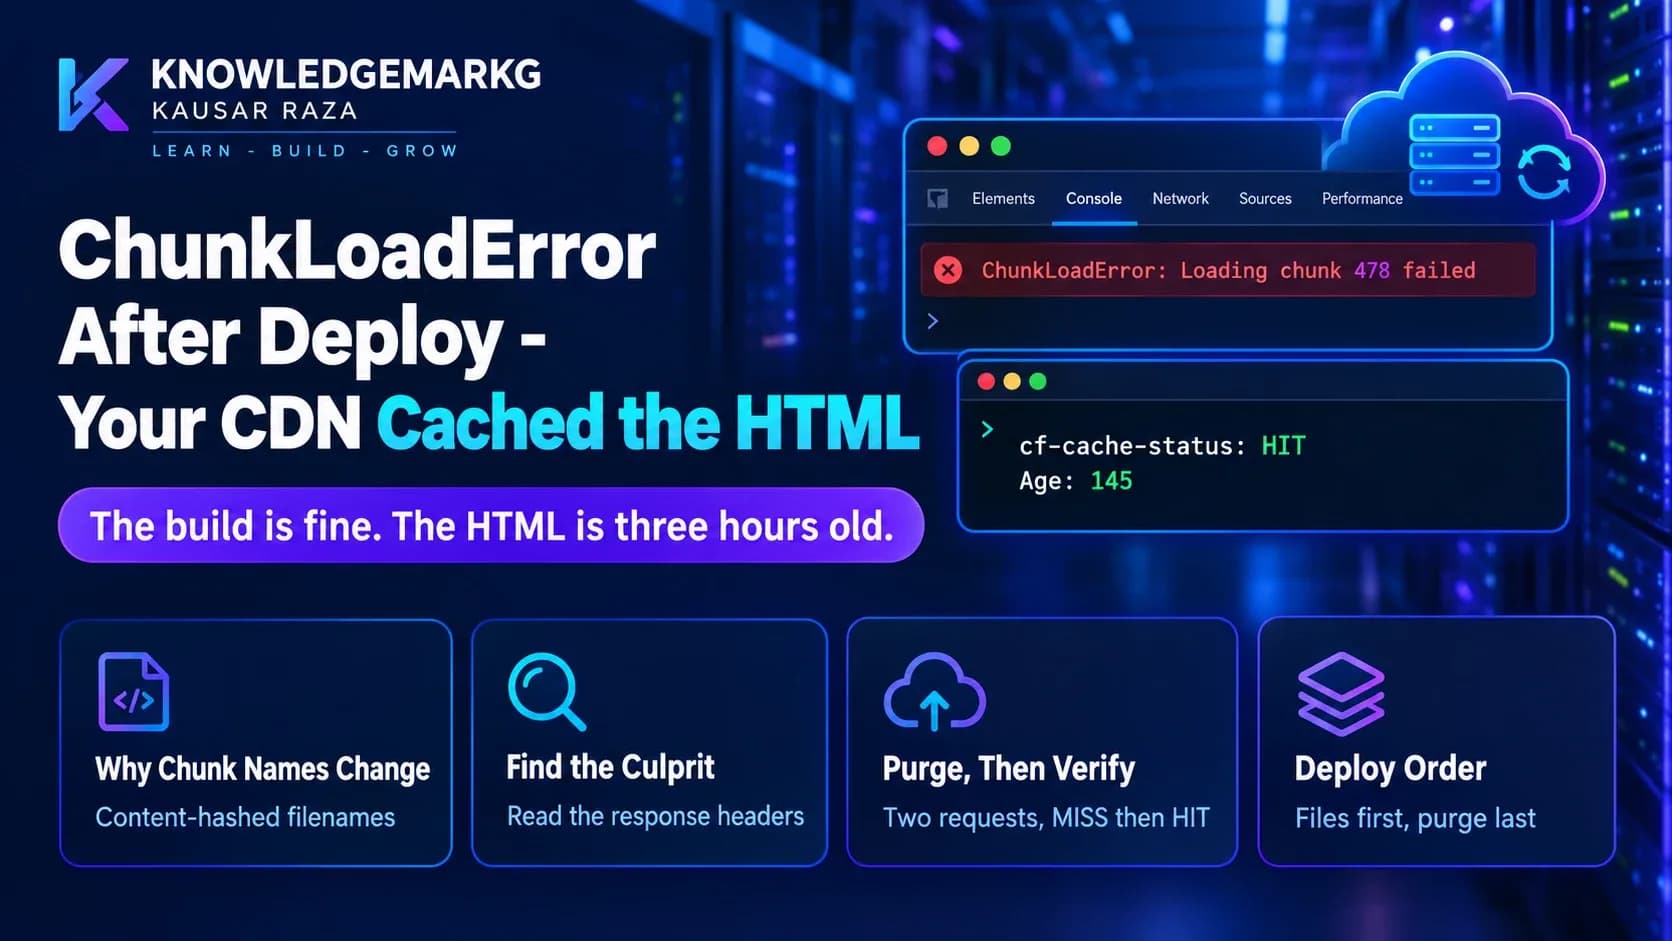
You deploy. The site comes back with no styling, or half the interactive bits are dead, and the console says:
ChunkLoadError: Loading chunk 478 failed.
(missing: https://example.com/_next/static/chunks/3ivcc6t1s04dh.js)
You check the server. The file is not there — but a file with a different name is, and it contains exactly the code that is missing. Rebuild, redeploy, same thing. Open the site in a private window and it is perfect.
Almost everything written about this error blames the service worker, or webpack's
output.publicPath, or tells you to catch the import and retry. On a Next.js site
behind a CDN the cause is usually none of those.
Why the chunk name changes every build
Next.js fingerprints its JavaScript. A real filename from this site:
/_next/static/chunks/3ivcc6t1s04dh.jsThat name is derived from the file's contents. Change one line of code and the chunk gets a new name, because the point of the hash is that the old URL can be cached forever and never go stale. It is a good design, and it has one consequence people forget: the HTML is the only thing that knows the current chunk names.
Every page ships a <script src> naming the exact chunks that build produced.
Deploy a new build and those names change. The old chunks are gone, because your deploy replaced
the folder.
So if a visitor is handed yesterday's HTML, it asks for yesterday's chunks, and yesterday's chunks 404. The browser calls that ChunkLoadError. Nothing is wrong with the build.
Who is handing out yesterday's HTML
Normally nobody. HTML is not supposed to be cached hard — that is what the hashed assets are for. But it is very easy to end up caching it by accident:
- A CDN cache rule that matches everything. This is what happened here. A
Cloudflare Cache Rule was added to cache HTML at the edge, with the edge TTL taken from the
origin's
s-maxage. It worked exactly as configured — including after a deploy. - A reverse proxy with
proxy_cacheon the HTML location. Same shape, different box. - A hosting panel's "performance" or "page cache" toggle, which usually means "cache HTML" without saying so.
- A service worker serving a cached shell. This is the one everyone writes about, and it is the least likely of the four if you did not add one deliberately.
One request tells you which world you are in:
curl -s -o /dev/null -D - https://example.com/ | grep -i 'cf-cache-status\|^age:'On this site that returns:
cf-cache-status: HIT
Age: 145
HIT means the HTML came from the edge, not from your app. Age is how
many seconds ago it was stored — and if that number is larger than the time since your deploy, you
have found your problem. Any CDN exposes an equivalent; look for X-Cache,
CF-Cache-Status, or a growing Age on repeat requests.
Narrowing it down in one pass
Four caches can produce this, and they need different fixes. The response headers separate them faster than reading any code:
| What you see | Which cache | Fix |
|---|---|---|
cf-cache-status: HIT, Age older than your deploy |
CDN edge | Purge the CDN |
No CDN header, Age grows on repeat requests |
A reverse proxy in front of the app | Stop caching HTML in the server block |
x-nextjs-cache: STALE or HIT |
Next.js's own ISR cache | Request again; or revalidate the route |
| Headers all look current, only some visitors affected | A service worker on their machine | Fix the worker's update strategy |
The service worker is the one every search result talks about, so it is worth saying plainly when it is the answer: only if you registered one. A Next.js app does not ship a service worker by default. If you added one through a PWA plugin and it uses a cache-first strategy for navigation requests, it will keep serving an old shell long after the CDN is clean — and the giveaway is that the problem follows particular people rather than particular pages. DevTools → Application → Service Workers, tick "Update on reload", and reload.
The fix, and the habit
The fix is one action: purge the CDN cache as the last step of every deploy. On Cloudflare that is Caching → Configuration → Purge Everything. Not "purge by URL" — you do not know which pages a visitor will land on, and every cached page is naming dead chunks.
Then prove it, because a purge that did not happen looks identical to one that did:
for i in 1 2; do
  curl -s -o /dev/null -D - https://example.com/ | grep -i cf-cache-status
done
The first request should be MISS (or EXPIRED) and the second
HIT. Two HITs in a row straight after a deploy means the purge did not take.
Pages that must never be cached should say so themselves rather than relying on a rule. On this
site /blog, /pricing and /search send
private, no-cache, no-store and show cf-cache-status: BYPASS. That is
worth checking deliberately — a logged-in page served from a shared edge cache is a much worse
problem than a missing stylesheet.
If you cannot purge as part of the deploy, do not cache the HTML. The hashed assets are where the win is anyway; caching the document saves a few milliseconds and costs you this.
Let the origin decide, not a dashboard rule
The sturdier version of this is to stop expressing the policy as a CDN rule at all, and send it from the application instead. Two headers do the whole job, and they say opposite things on purpose:
/_next/static/...   Cache-Control: public, max-age=31536000, immutable
/  (the document)   Cache-Control: public, s-maxage=300, stale-while-revalidate=...
The first is safe precisely because the filename contains a hash — a given URL's contents can never change, so a year is not a risk. The second lets the edge hold the document briefly and serve a slightly stale copy while it fetches a new one, which is the behaviour you actually want between deploys.
A CDN configured to respect the origin then needs no per-site rules, and a page that must never
be cached can opt out by itself. That is how /blog on this site ends up
BYPASS — it sends no-store, and nothing in a dashboard has to remember
that it is special.
It still does not remove the need to purge after a deploy. Even a 300-second edge TTL is 300 seconds of visitors being handed dead chunk names.
A deploy order that does not produce this
- Build with a cold data cache —
rm -rf .next/cache/fetch-cachebeforenpm run build, for the reason in the next section. - Check the build output matches reality before shipping it. Count the pages it prerendered against what you expect.
- Upload the new files, leaving the old ones in place where you can. Hashed chunks have unique names, so the old and new sets can coexist — and a visitor mid-session still holding old HTML keeps working.
- Purge the CDN. Last, after the files are live, never before.
- Verify with two requests, as above.
Step 3 is the one people skip because deleting everything feels cleaner. It is also the step that turns a five-minute window of broken pages into none, and on this stack deleting the whole folder has already cost real data once.
The same bug wearing a different hat: a stale build cache
There is a second way a deploy ships something old, and it catches people who have already fixed the first one.
Next.js keeps the data it fetched during a build in .next/cache/fetch-cache, and
that directory survives between builds. A fetch with
revalidate: 3600 that was made an hour ago is still considered fresh, so a brand new
build can prerender pages from the previous build's API responses.
I reproduced this an hour before writing this post. A build run with a warm cache prerendered 38 tool pages. The live API returns 54. The code was correct; the build was answering from a cached copy of the catalogue. Deleting the directory and rebuilding produced all 54.
rm -rf .next/cache/fetch-cache
npm run build
Nothing warns you. The build succeeds, exit code 0, no warnings — it just quietly ships a sitemap that is missing a third of your pages. If your build fetches a catalogue, a menu or a list of posts, clear this before a release build.
The pattern worth keeping
Three times now on this site a "deployment bug" has turned out to be something cached: a page that would not update was Next.js's own cache serving STALE, a half-updated site was Windows locking files the running app had open, and this one was the CDN.
The habit that catches all of them: when a deploy produces a result that makes no
sense, read the response headers before you read your code. cf-cache-status,
x-nextjs-cache, age and etag will tell you in one request
whether you are even looking at the build you just shipped. Most of the time you are not, and
there is no bug to find.
Join the conversation
No comments yet — be the first to share what you think.