

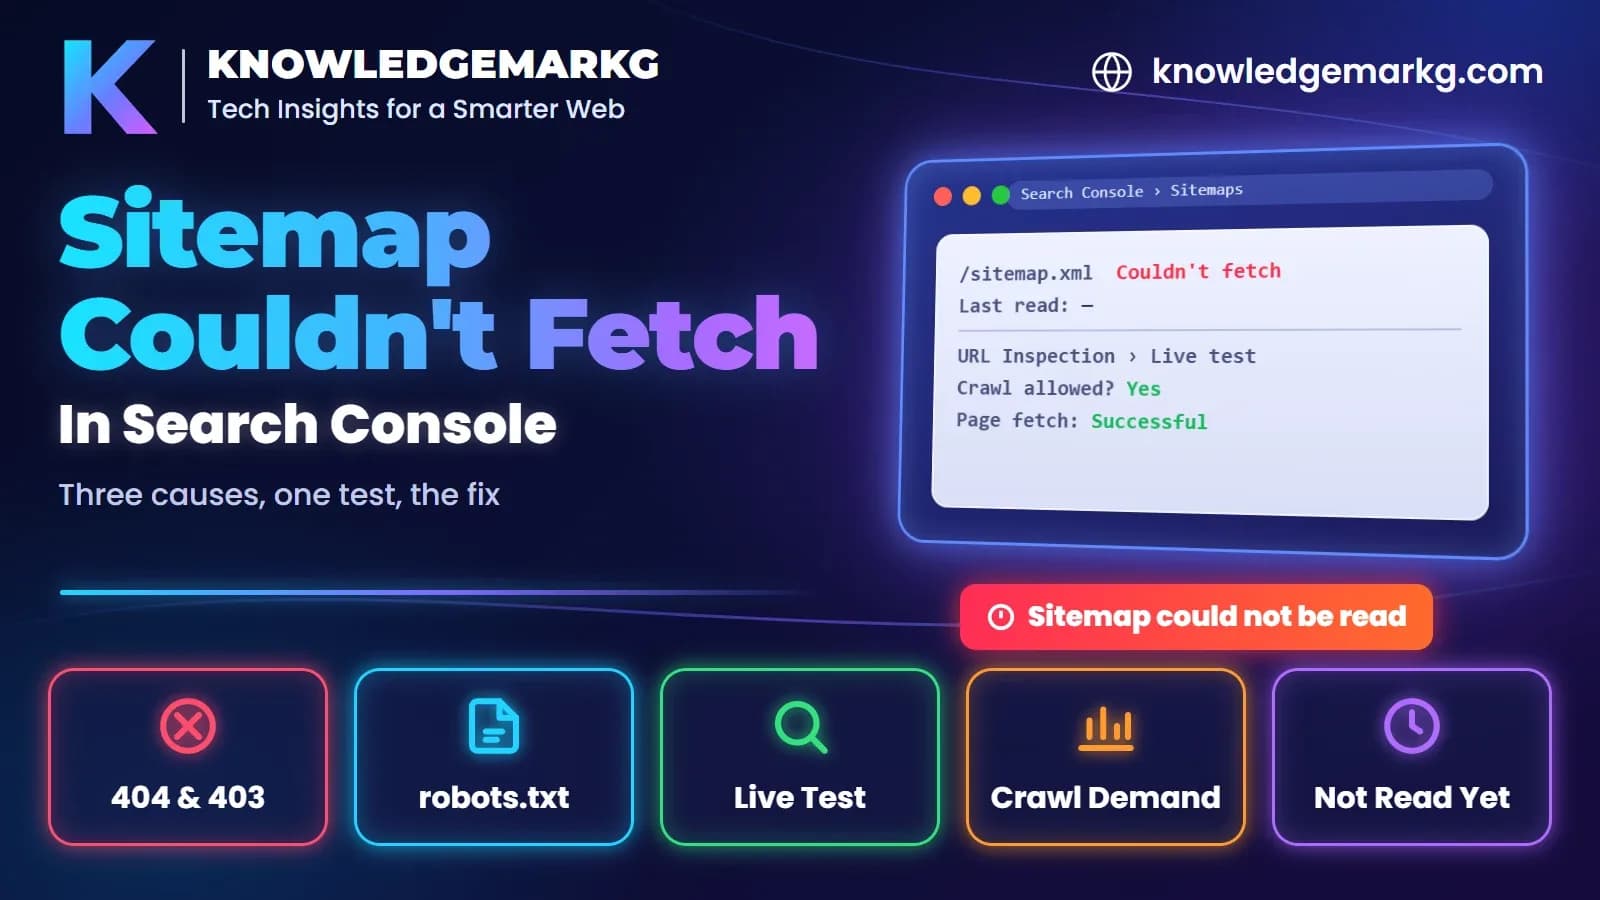
You submit your sitemap in Google Search Console and the status column says Couldn't fetch. Open it and the detail reads "Sitemap could not be read". You open the same URL in your browser and it loads fine. So what is Google talking about?
The short answer: "Couldn't fetch" is one label for three different situations, and only one of them is a problem with your file. Google's own people said so on their podcast in October 2026. Below is how to tell which one you have, the fix for each, and what this site's sitemaps look like in Search Console right now, so you can compare yours against a working setup.
What a working setup looks like
This is the Sitemaps report for knowledgemarkg.com, read on 16 November 2026:
Sitemap                  Type           Last read      Status    Discovered pages
/sitemap.xml             Sitemap index  Nov 16, 2026   Success   239
/page-sitemap.xml        Sitemap        Nov 14, 2026   Success   121
/post-sitemap.xml        Sitemap        Nov 14, 2026   Success    65
/post_tag-sitemap.xml    Sitemap        Nov 15, 2026   Success    35
/portfolio-sitemap.xml   Sitemap        Nov 12, 2026   Success    11
/category-sitemap.xml    Sitemap        Nov 12, 2026   Success     6
Two details are worth copying. The index's 239 discovered pages are exactly the sum of its children (121 + 65 + 35 + 11 + 6, plus 1 from an author sitemap that sits in the index but was never submitted on its own). And the "Last read" dates differ per file. Google re-reads each sitemap on its own schedule, which has nothing to do with when you submitted it or how often your pages are crawled.
"Couldn't fetch" means one of three things
- Google tried and failed. A real fetch error: 404, 403, a robots.txt block, a 5xx, a firewall challenge, a timeout. This is the only case where changing your server fixes it.
- Google didn't try, or gave up early. In Search Off the Record episode 114 (published 1 October 2026), Martin Splitt said he regularly gets emails about sitemaps that validate but still show "couldn't fetch". John Mueller gave two reasons. Google may be too busy to fetch it (host load), or it sees no need to crawl more from the site (crawl demand). Both are reported with the same label. He added that crawl demand is often based on the site's perceived quality, so it's "not purely a technical thing". Google's help page lists "low crawl demand" among the causes too.
- It hasn't been processed yet. A newly submitted sitemap with no "Last read" date can sit in this state for days. That isn't an error, and Google hasn't rejected anything.
Most guides only cover the first case. If yours is the second, then renaming the file, resubmitting it ten times or switching plugins will do nothing. That's why the same advice keeps failing in forum threads.
Step 1: find out which case you're in
Do these in order. Each one rules something out.
Check the URL you submitted, byte for byte
Click the sitemap row in the report and look at the exact address. Submitting the www version, the
http:// version or a version with a trailing slash means Google requests a URL that redirects
(or 404s) instead of the file. Here's what the variants of this site's sitemap return:
== https://knowledgemarkg.com/sitemap.xml
HTTP/1.1 200 OK
Content-Type: application/xml; charset=utf-8
Cache-Control: public, max-age=3600, stale-while-revalidate=86400

== https://www.knowledgemarkg.com/sitemap.xml
HTTP/1.1 301 Moved Permanently
location: https://knowledgemarkg.com/sitemap.xml
Server: cloudflare

== http://knowledgemarkg.com/sitemap.xml
HTTP/1.1 301 Moved Permanently
Location: https://knowledgemarkg.com/sitemap.xml

== https://knowledgemarkg.com/sitemap.xml/
HTTP/1.1 308 Permanent Redirect
location: /sitemap.xml

== https://knowledgemarkg.com/sitemaps.xml
HTTP/1.1 404 Not Found
Content-Type: text/html; charset=utf-8
Only the first one is the file. Submit that exact URL: the final https address on the hostname your
Search Console property uses. A typo like sitemaps.xml is a plain 404, which Google reports as
"Couldn't fetch" and "General HTTP error". Note too that a sitemap only covers URLs on the same host and
protocol. If your sitemap lists https://www.example.com/ pages and you've verified
https://example.com/, the details show "URL not allowed".
Check status, content type and robots.txt with curl
# Status, content type and any redirect for the exact URL you submitted.
curl -s -o /dev/null -D - "https://example.com/sitemap.xml" \
  | grep -iE '^HTTP|^content-type|^location|^x-robots-tag|^server'

# Is the sitemap itself blocked in robots.txt?
curl -s https://example.com/robots.txt

# Does it parse? (xmllint ships with libxml2; on Windows use the validator linked below)
curl -s "https://example.com/sitemap.xml" | xmllint --noout - && echo "well-formed"
You want a 200, an XML content type (application/xml or text/xml), no
location header, no X-Robots-Tag: noindex in front of something odd, and a robots.txt that
doesn't Disallow the sitemap's path. If robots.txt blocks it, Google says you "must remove the rule".
Nothing else will work until you do.
Don't trust a curl with a Googlebot user agent
Plenty of guides tell you to do this:
# This does NOT test what Googlebot gets.
curl -s -o /dev/null -w "%{http_code}\n" \
  -A "Mozilla/5.0 (compatible; Googlebot/2.1; +http://www.google.com/bot.html)" \
  https://example.com/sitemap.xml
A 200 here proves nothing. Your request comes from your IP, not Google's, and firewalls and bot filters judge
the IP as well as the user-agent string. A CDN that verifies Googlebot by IP can let real Googlebot through and
block your fake one, or the other way round: a rule written against Google's IP ranges never fires for you. This site returns 200 to a Googlebot user agent, to
python-requests and to plain curl, and that still tells me nothing about what Google itself
gets.
The test that counts: URL Inspection on the sitemap URL
Paste the sitemap's URL into the Inspect any URL box at the top of Search Console and click Test live URL. Ignore the "URL is not on Google" message; a sitemap isn't supposed to be indexed. Look at two lines under the crawl details:
- Crawl allowed? should be Yes. A No means robots.txt.
- Page fetch should be Successful. Anything else is a real fetch failure, and the message beside it (not found, server error, blocked, redirect) tells you which.
This is the only check that comes from Google's own crawler. Google's help page recommends it for exactly this case.
Read the verdict
- Live test fails: case 1. Go to step 2.
- Live test passes, the sitemap was submitted days ago and "Last read" is empty: case 3. Wait a week.
- Live test passes and it has said "Couldn't fetch" for weeks: almost certainly case 2. Go to step 3.
Step 2: fix a real fetch failure
- 404. Wrong URL, or the plugin that generates it is off. WordPress SEO plugins move it:
/sitemap_index.xml(Yoast, Rank Math) versus/wp-sitemap.xml(WordPress core). This domain ran WordPress before it moved to Next.js, and the old/sitemap_index.xmladdress still answers for that reason. - 403 or a challenge page. A firewall rule is blocking Google. Check custom WAF rules, country blocks, rate limits and "under attack" modes at your CDN or host. A fake-Googlebot curl won't reproduce it, so check the firewall's event log for requests to the sitemap path instead.
- 5xx or timeouts. A sitemap generated on every request can be slow on a large site or a cold
server. Cache it. This site's sitemaps are route handlers sent with
Cache-Control: public, max-age=3600, so Cloudflare serves most requests without touching the origin. Check Settings → Crawl stats in Search Console for server errors and host status. - HTML instead of XML. A login page, a "coming soon" page or a single-page app's shell returned with a 200. Google can't parse it as a sitemap. A store or site behind a password page is the common case.
- Too big. One file holds at most 50,000 URLs and 50 MB uncompressed, and must be UTF-8. Split it and list the parts in a sitemap index:
<?xml version="1.0" encoding="UTF-8"?>
<sitemapindex xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">
  <sitemap>
    <loc>https://example.com/post-sitemap.xml</loc>
    <lastmod>2026-11-14T02:45:53Z</lastmod>
  </sitemap>
  <sitemap>
    <loc>https://example.com/page-sitemap.xml</loc>
  </sitemap>
</sitemapindex>
An index can't list another index, and every <loc> must be a full absolute URL.
After the fix, resubmit. Google says a failed sitemap is retried "for a few days" and then dropped, so a sitemap that failed weeks ago needs a manual resubmit even once it's healthy.
Step 3: when nothing is technically wrong
If the live test passes and the status hasn't changed for weeks, Google is choosing not to spend time on the file. Answering a Reddit thread in February 2026 about exactly this, Mueller said Google has to be keen on indexing more content from the site, and won't use the sitemap if it isn't convinced there's new, important content.
That moves the fix away from the sitemap:
- Don't keep resubmitting or renaming it. The file isn't the problem. Renaming only creates a second entry in the report.
- Look at what's in it. A sitemap full of thin tag pages, near-duplicate pages or URLs that redirect or say noindex teaches Google that the file is worth little. Remove anything you wouldn't want to land on from a search.
- Link to your important pages. Links from your home page and from pages Google already crawls carry discovery without the sitemap.
- Request indexing for a handful of key URLs through URL Inspection. The quota is about ten a day.
- Compare with Bing. If Bing Webmaster Tools reads the same file fine, you've confirmed it's Google's choice and not your server.
A sitemap is a hint, not a requirement. A small, well-linked site gets crawled with or without one. If "Couldn't fetch" sits next to pages that are being indexed anyway, it costs you nothing. The more useful report is Page indexing, and if your pages are stuck there instead, see Crawled vs Discovered - currently not indexed.
Shopify and Blogger
Both generate the sitemap for you at /sitemap.xml. You can't edit the file, so a real fetch failure
is rare. Common causes are submitting the wrong domain (the myshopify.com or blogspot.com
address instead of your custom domain, or the reverse) and, on Shopify, a store still behind its password page,
which Google can't get past. If neither applies, you're almost certainly in case 2 or 3 and the advice above
holds.
A note on caching
If a CDN caches your sitemap, it can serve a stale copy or a cached error. A 404 that's fetched before the file exists can be served for minutes afterwards. That happened on this site with a blog post, as described in does Cloudflare cache 404 responses. After fixing the sitemap, purge it from the CDN before you resubmit.
Check it in one go
The free XML Sitemap Validator fetches a sitemap or index the way a
crawler would and reports the HTTP status, content type, XML errors, the namespace, relative or off-host URLs,
duplicates, bad lastmod dates, and whether robots.txt points at it. Then run the
robots.txt validator to make sure the pages it lists aren't blocked, and
the redirect checker on any URL you're unsure of. For Bing and Yandex, which
take sitemaps and IndexNow pings, see what IndexNow's
202 really means.
Join the conversation
No comments yet — be the first to share what you think.